Synthetic Data Generation for Low-Resource Eval Scenarios
Synthetic test data helps teams catch AI failures before production reaches real users.
Real labeled data is chronically scarce, costly, and legally constrained, and that scarcity has become the inflection point driving synthetic data adoption across AI evaluation, DataOps, and revenue operations at the same time. Unlabeled data piles up in every production system, but the annotation work that turns raw records into usable ground truth stays slow and expensive, so teams end up with abundant inputs and a thin layer of trustworthy test coverage sitting on top of them. In regulated industries, the problem compounds: real data frequently cannot legally enter a test environment. Paytient's reliance on Tonic.ai's data de-identification system for sensitive health and payment information is a case of a team with no other route to building eval coverage, because the real records themselves were legally off-limits for that purpose.
The cost of skipping this work is not abstract. FutureAGI's 2026 synthetic data glossary describes a voice-agent team that expanded into a new market and only discovered, after launch, that its ASR system mishears 20% of region-specific names, a failure that a synthetic cohort built ahead of time would have caught in an afternoon. That example captures the deeper mechanism: when an AI system runs on flawed or incomplete inputs, it does not simply underperform on a handful of edge cases. It reinforces the error at scale, shipping the same mistake to every user who shares that edge case, until someone notices in production. Eval gaps are a business risk, because undetected failure modes reach real users and real revenue before anyone has a chance to catch them in a controlled setting.
Synthetic data and the training/eval distinction
Synthetic data for evaluation means machine-generated test coverage: personas, scenarios, queries, conversations, and tool-calling traces built to expose edge cases and failure modes that production logs have not yet produced. The purpose is cohort realism, not volume for its own sake. Confusing this kind of synthetic data with synthetic training data is the costliest mistake a team can make, and FutureAGI's 2026 guide draws the line precisely: synthetic training data exists to expand the training distribution, while synthetic eval data exists to expand the test distribution. The risks on each side are different in kind. On the training side, the danger is memorization of eval content and artificially inflated scores. On the eval side, the danger is test-set contamination that produces false confidence at release.
The failure mode is concrete and avoidable. If eval personas leak into any training corpus, benchmark scores climb, but the genuine safety coverage those personas were built to provide quietly disappears. FutureAGI describes a hash-isolation rule as the one governance pattern that holds up once an organization has scaled past a couple of post-training pipelines: eval personas live in an immutable store, never enter a training corpus, and a CI check fails automatically if they turn up in a training mix anyway. A related safeguard reinforces the same boundary structurally: the pipeline that generates synthetic training data should run as a different binary from the one that generates synthetic eval scenarios, ideally built on the same library but a different config, a different model family, and a different team.
This distinction matters more in 2026 than it would have a few years earlier, because agent architectures have changed what a meaningful eval actually has to test. Single-turn question-and-answer datasets do not exercise the agent loop, the planner, the tool-call sequence, or memory. Persona-based synthetic scenarios do. This format has become the dominant approach for agent and voice-agent evaluation. Public benchmarks, meanwhile, have lost much of their diagnostic value for exactly the reason the training/eval distinction warns against: frontier models are now trained on heavy synthetic mixes, so contamination of public benchmarks is the default assumption rather than the exception. Serious teams treat public benchmarks as a coarse tier filter and build private synthetic eval suites as the real release gate.
Generation methods teams use to build synthetic eval coverage
No single generation method covers every low-resource scenario, and the right choice depends on the kind of scarcity a team is facing: linguistic, domain-specific, or structural. Each method trades off inference cost, diversity, and fidelity to real-world distributions, and these tradeoffs are well documented, not theoretical.
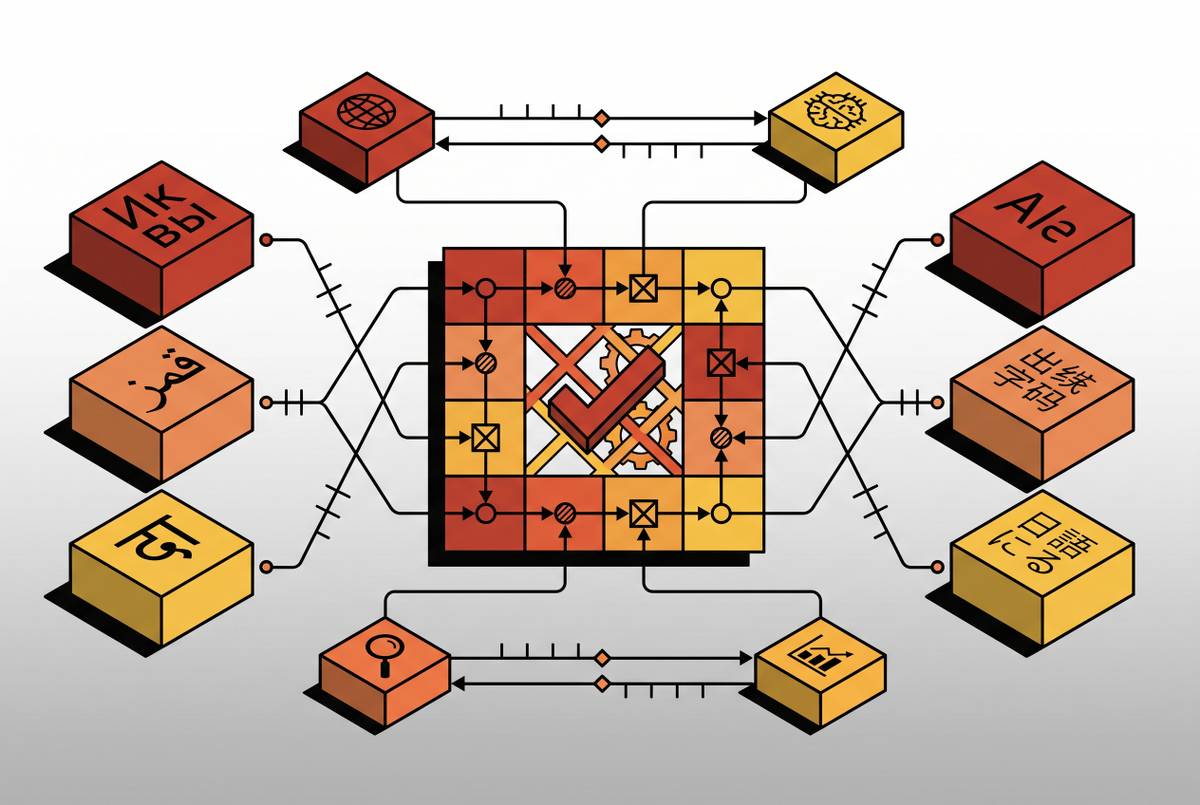
If you need a low-resource language baseline, use few-shot prompting with target-language examples; it remains the strongest. Research from the Kempelen Institute and DFKI confirms that teams get the strongest downstream results for language classification work this way. The tradeoff raises inference cost and risks lexical anchoring, where generated text skews toward the vocabulary and sentence patterns of the seed examples rather than capturing the fuller range of the target language. You can use it if you already hold a small number of genuine target-language examples and need fast augmentation for classification tasks like sentiment or intent detection.
Activation steering offers an alternative built around named strategies, Language Steering and Quality Steering. Kempelen Institute and DFKI research introduces both: Language Steering targets a language's linguistic identity directly, while Quality Steering contrasts human-written text against backtranslated text to capture well-formedness. Applying either to early layers of a model consistently improves the diversity of generated data and often strengthens downstream performance, particularly for low-resource languages. The method's chief advantage over few-shot prompting is that it works in zero-shot settings, so it cuts inference cost while matching or beating few-shot diversity. Quality steering vectors also turn out to be largely language-agnostic: most evaluated languages show strong negative cosine similarity between Quality and Language vectors, so the quality signal does not get tangled up with any one language's representation. So if you work in zero or near-zero resource settings, or run generation jobs so large that few-shot inference costs become prohibitive, this approach fits.
LLM-based forward translation addresses machine translation and multilingual coverage specifically. Research out of the University of Helsinki and Cambridge shows that forward-translating high-resource monolingual corpora into low-resource languages, using a sufficiently capable LLM, produces synthetic parallel data that trains competitive MT models from scratch and consistently improves pretrained systems. The gains hold even when the synthetic parallel data is noisy, and the effect is strongest for the least-resourced languages in the spectrum. This method suits teams adding coverage for a new language or region where no parallel corpus exists.
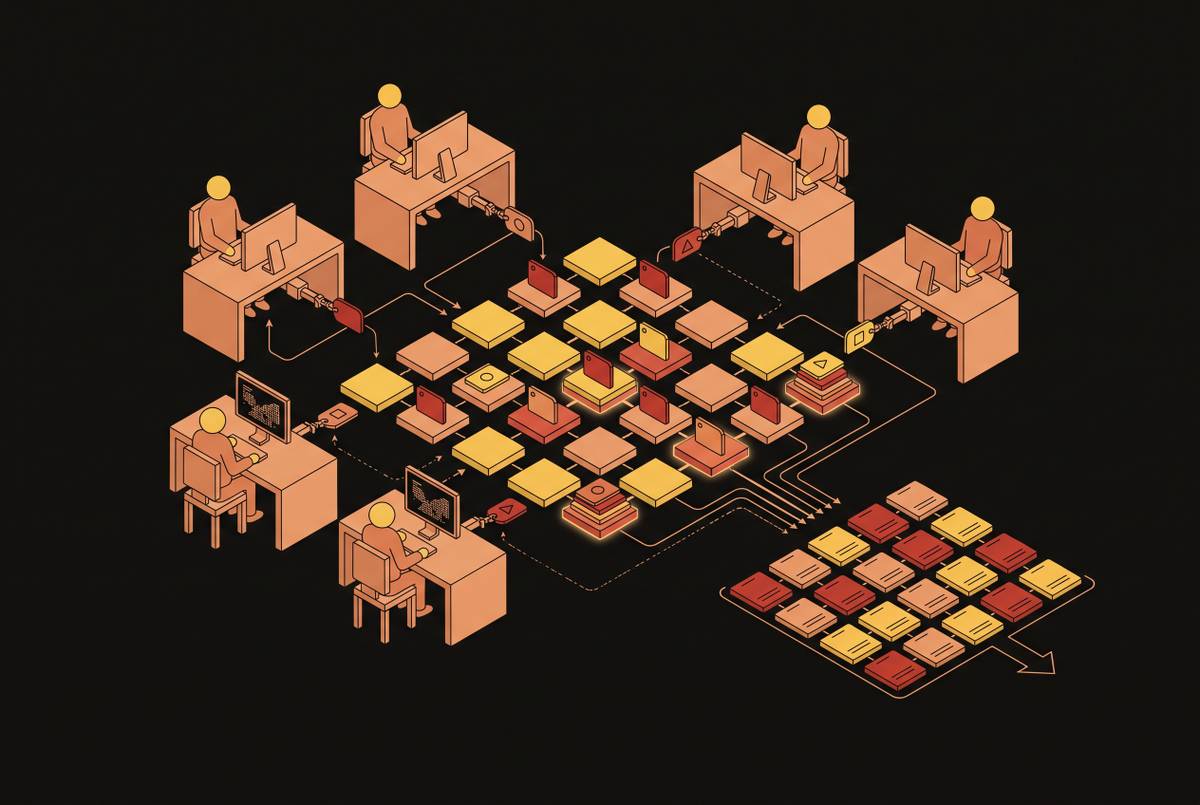
Persona-and-scenario generation is the dominant pattern for building eval cohorts in agent and voice-agent systems, as FutureAGI's 2026 guide describes. It fits teams building or maintaining agent systems whose failure modes live in the interaction loop rather than in any single response, which is precisely the gap single-turn datasets leave open.
Tabular and structured record generation handles a different kind of scarcity: schema-consistent, privacy-sensitive data for pipeline and model testing. ING Belgium used DataCebo's SDV Enterprise, built on the Synthetic Data Vault, to generate a large set of synthetic payment records in minutes, demonstrating that tabular financial data, often the hardest category to share across teams for privacy reasons, can be produced at speed for testing purposes. Data and RevOps teams can use this method if they need PII-free records for testing AI scoring models, deduplication logic, or pipeline integrity without exposing real customer data.
Scenario-driven simulation extends the same logic into physical domains. Research from Gustave Eiffel University proposes a modular, scenario-driven framework for generating synthetic datasets to evaluate visual perception under adverse driving conditions, built on the Pro-SiVIC and RTMaps platforms. The framework follows a three-stage structure: configuring use-case-driven scenarios, generating sensor data and ground truth through simulation, and post-processing for usability, which shows that the scenario-first design pattern common in NLP transfers directly to physical-world perception problems. So this approach fits teams in autonomous systems or robotics who face rare adverse conditions, weather extremes or unusual road scenarios, that they cannot collect safely or in sufficient volume from real-world driving.
Rejection sampling with a teacher model, the pattern associated with Meta's approach, rounds out the set. It suits teams generating reasoning traces, QA pairs, or code examples where an automated quality filter can stand in for manual review, scaling the volume of usable synthetic eval cases without a proportional increase in human review effort.
How much synthetic data helps in low-resource settings
Synthetic augmentation reliably improves performance in low-resource eval scenarios, but the size of that improvement is bounded, and it depends heavily on how little real data a team starts with. Research published in Computational Linguistics confirms that when human-annotated data is limited, synthetic augmentation can improve model performance, and the effect is strongest when real data is scarcest. The University of Helsinki and Cambridge research on machine translation reinforces the same pattern from a different angle: even noisy LLM-generated synthetic data trains competitive models from scratch and consistently improves pretrained systems, and smaller fine-tuned models trained on this synthetic data can match or outperform much larger models, which points to a ceiling tied to data quality rather than model scale.
The honest objection deserves to be stated. If real data is abundant, models trained or evaluated with synthetic data struggle to fully match the performance real data achieves, so synthetic coverage matters most when real data is scarcest. Once a well-annotated production corpus exists in sufficient volume, you should not expect synthetic eval data to substitute for it. But the low-resource regime is exactly where the hardest eval gaps live, and a partial gain in coverage, catching a class of failures that would otherwise reach production undetected, counts as a meaningful reduction in risk rather than a marginal improvement. The practical response is to treat synthetic eval coverage as a complement that shrinks in importance as real data accumulates and to track that ratio explicitly as part of eval suite governance.
Validation: how to know whether synthetic eval data is trustworthy enough to act on
Generating synthetic eval data accomplishes only half the task. The output has to be checked against real-world coverage, diversity, and cohort-match criteria before any team treats it as a release gate, and the right check depends on which generation method produced the data.
For synthetic text used in NLP and agent evals, research in Computational Linguistics proposes desiderata that map directly onto eval use cases: label adherence, that generated samples respect their intended class; well-formedness, that the text is grammatically and stylistically sound; and diversity, that the output is not lexically anchored to its seed examples. Lexical anchoring is the failure mode most tied to few-shot prompting specifically, and the standard check against it is diversity analysis across the embedding space rather than a simple read-through. Kempelen Institute and DFKI research uses cosine similarity between steering vectors alongside embedding-space analysis as its own diagnostic, and teams working with activation steering should run an equivalent representational check before treating that output as production-grade.
Agent and persona evals call for a different kind of validation. FutureAGI's 2026 guide specifies that synthetic eval data has to pass a human spot-audit along with a production-cohort match, which tests whether the synthetic cohort exercises the same distribution of intents, failure modes, and edge cases that the real user population produces. That match matters most precisely in the cases synthetic data was built to solve: shipping into a new region or customer segment where production logs provide zero coverage. There, the synthetic cohort stands in for data that does not yet exist, so its validity has to be checked against the closest adjacent distributions available rather than against the target population directly, since that population has not generated any real signal yet.
Each generation method carries its own blind spot, and none of them substitutes for the check built for a different one. Few-shot prompting needs a diversity audit against lexical anchoring. Activation steering needs representational analysis in embedding space. Persona and scenario generation needs a human spot-audit paired with a production-cohort match. Tabular and simulation-based methods need their own fidelity checks against the schemas and sensor outputs they are meant to reproduce. Treating any one of these checks as sufficient for every method is how a team ends up trusting a release gate that was never actually validated for the failure mode that eventually reaches production.
Sources
- Want Better Synthetic Data? Steer It: Activation Steering for Low-Resource Language Generation
- Evaluating Synthetic Data Generation from User Generated Text
- What Is Synthetic Data for LLM Eval? FutureAGI Guide (2026)
- Scenario-Driven Synthetic Data Generation Framework for Visual Perception Evaluation Under Adverse Driving Conditions - PMC
- Scaling Low-Resource MT via Synthetic Data Generation with LLMs
- A Rigorous Evaluation of LLM Data Generation Strategies for Low-Resource Languages