Eval Harness Orchestration With Open-Source Frameworks
Turn eval harnesses into production gates using the right framework and orchestration topology.
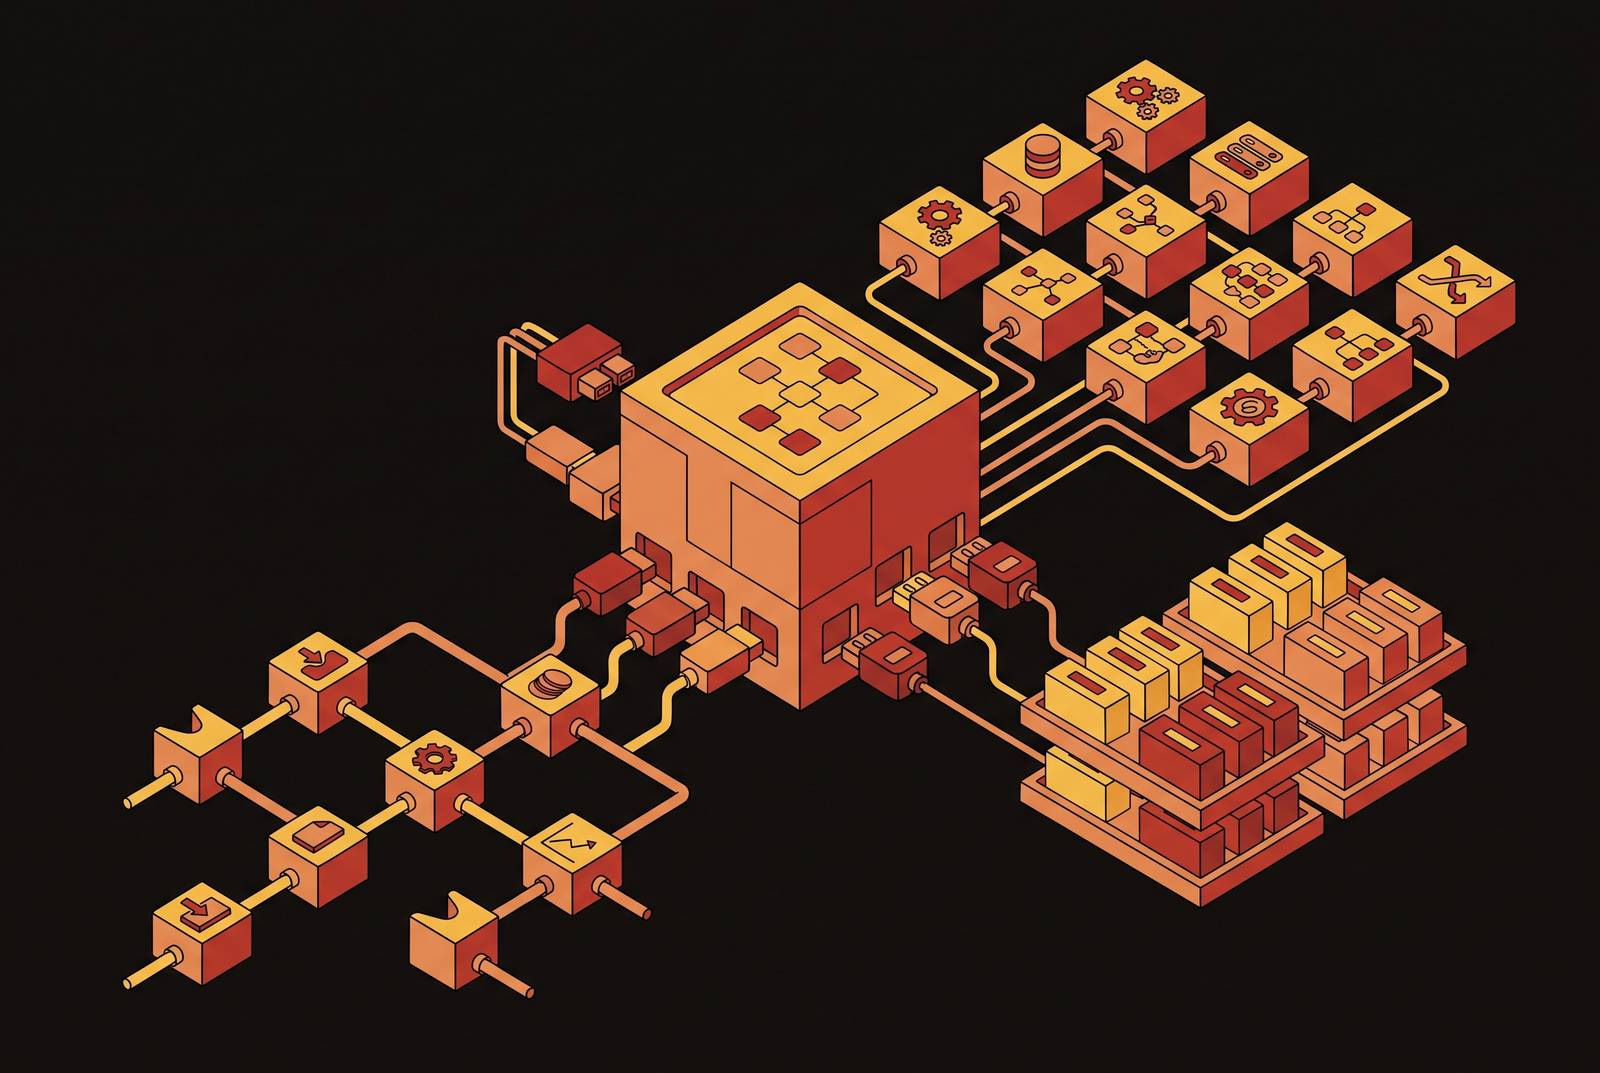
Eval harness orchestration with open-source frameworks is the engineering work that turns AI evaluations into dependable production gates. The decisive choice is a framework’s fit with an orchestration architecture, a CI trigger model, and validated evaluators. A harness succeeds when it can detect meaningful regressions reproducibly and fast enough to govern releases.
Why eval harnesses are now an engineering discipline, not an afterthought
LLM eval harnesses now occupy the same structural role in AI pipelines that pytest, JUnit, and RSpec occupy in traditional software. They live in CI, gate builds, and return a pass/fail exit code that allows or blocks a system’s advance. As AI systems enter production, informal spot-checking cannot catch regressions in model behavior, prompt sensitivity, and tool-use correctness at the cadence releases demand. Versioned test suites, threshold gates, and reproducible runners turn those checks into an engineering discipline.
Open-ended generation does not fit neatly into traditional statistical metrics. LLM-as-a-judge methods offer more flexibility, but their reliability depends on the judge model, prompt, and evaluation strategy. The harness therefore has to manage both execution and the quality of the measurement itself. The choice of framework and orchestration architecture are now separate engineering decisions, and both affect how well a release gate can be trusted.
The five framework styles the open-source ecosystem has settled on
With the pytest-style approach, evaluation runs inside familiar Python test functions that call assertions directly. DeepEval is the canonical example, integrating with existing pytest infrastructure and offering G-Eval, DAG, RAG, agent, conversational, and safety metrics under Apache 2.0. Its fit is strongest where Python tests already define the engineering workflow and broad metric coverage supports testing within that workflow without a separate configuration format.
Promptfoo declares evaluation in a single config file, runs through a CLI command, and bundles red-team plugins. This works well for prompt regression testing and gives non-engineers a format they can read and change without having to work inside Python test functions.
The interactive and platform-bundled style works for teams that are developing evaluations before they set up a CI gate. UpTrain runs evaluations in Jupyter and ships an OSS dashboard, while MLflow Evaluate runs through mlflow.genai.evaluate() calls and connects evaluation to MLflow Tracking and prompt and model comparison. These approaches fit interactive data science work or stacks built on a data science platform, but the interactive workflow is separate from a decision that can block a build.
The task-decorator style organizes the work around the evaluation task itself. Inspect AI defines tasks as decorated functions or pipelines and supports async tool-use and sandboxed execution, so it works well when evaluation needs to test a tool-use loop. Ragas serves the more focused retrieval-quality use case through RAG-specific metrics including Faithfulness, Context Recall, Context Precision, Answer Relevancy, and Answer Correctness.
The platform approach with a framework-style eval API connects offline testing to production scoring. FutureAGI provides an Apache 2.0 platform whose metrics are callable from Python or pytest, with the same metric contract running offline in CI and online through span-attached scoring, plus built-in gateway gating. Its fit is production work where evaluation, tracing, simulation, and runtime guardrails need a shared scorer contract.
What an eval harness actually requires to function as a CI gate
A framework becomes a CI gate only when its interfaces can turn evaluation results into an enforced decision. Test definition must use a consistent way to write input, expected, and context tuples and the assertions that must hold. Scoring requires a maintained metric library and a hook for custom metrics, so the suite can measure the failure modes relevant to the system. The runner must run that suite and return a deterministic pass/fail exit code. Configurable threshold gating must fail the build when the suite falls below its required pass rate.
That decision also needs an inspectable record. Human-readable reports in HTML, a terminal, or a dashboard make failures understandable, while machine-readable exports in JSON or Markdown support downstream consumers. Trace integration must expose results as spans or attributes so an observability platform can correlate evaluation outcomes with production behavior.
Throughput and evaluator reliability are the two requirements easiest to overlook. A runner that takes too long risks being bypassed, regardless of how complete its metric library is. A judge that misses the failures it is meant to catch can return a clean result while doing little to protect the build. EvalSense tests evaluator reliability through controlled perturbations that check how the evaluator behaves before the judge is trusted to gate a build.
Why orchestration topology — not just framework choice — determines evaluation quality at scale
Once evaluation spans multiple models, prompt variants, tasks, or deployment environments, the connections between tasks become a performance variable. Unlike an ordinary pytest run, LLM evaluation has to account for inference latency, rate limits, and non-determinism. A topology determines which tasks wait, which share inference capacity, and which require specialized execution.
Sequential execution runs each task after the previous one completes, making the pipeline simple to understand and debug. As the suite grows, its latency adds up. Parallel execution reduces wall-clock time by running independent tasks concurrently, but token budgets, rate limits, and inference backend capacity constrain that concurrency.
Hierarchical execution introduces a coordinator that dispatches work to specialized sub-runners. This lets unit-style tests, sandbox-executed tasks, and LLM-judged evaluations coexist without forcing every task into one framework. Hybrid or task-adaptive execution goes further by using dependency graphs to choose a topology for each task. These arrangements address differences in evaluation work as well as the number of tests.
AU-Harness provides a concrete example of why these mechanics matter. It achieved a 151% relative improvement in samples per second over a naive baseline through optimized batch processing and parallel execution. Its approach includes token-based request scheduling, vLLM batching and dataset sharding, adaptive retry mechanisms, and layered request synchronization. When teams instead let a sequential suite grow until they run it only on release branches or skip it, evaluation stops being a routine gate.
How eval harnesses plug into CI pipelines: the integration patterns that work
A workable CI integration aligns the framework idiom, orchestration topology, and trigger model. Commit-triggered evaluation runs on every push, so it depends on a suite fast enough to return within the time engineers will wait. Parallel execution or a threshold-gated subset can make that pattern viable. PR-triggered evaluation with baseline comparison instead checks the candidate branch against a stored baseline, so it can catch regressions without running the full suite on every commit.
Nightly evaluation accommodates slow, comprehensive work, including full benchmark suites powered by lm-evaluation-harness, but does not block merges or catch regressions before they ship. With release-gated evaluation, the suite is the last check before a deployment artifact is promoted. That pattern fits safety-critical evaluations and sandbox-executed capability tests.
The framework's interfaces control how these trigger choices reach the runner. DeepEval works in existing pytest CI jobs, so threshold configuration and results go into the test reporting infrastructure already in place. Promptfoo expresses the evaluation through its configuration and CLI runner.
Those comparisons require reproducibility: AU-Harness identifies ad-hoc prompting and non-standardized evaluation settings as reasons results become incomparable across runs. Standardized prompting protocols and fixed configurations are therefore prerequisites for separating regressions from noise. Trace integration then connects the build decision to production behavior, allowing CI failures to be correlated with production anomalies.
Meta-evaluation: how to know whether your evaluator is actually measuring what you think
An efficient pipeline still rests on an unproven assumption if its judge has never been tested. EvalSense makes that problem concrete by showing that evaluator reliability varies with the task, judge model, and evaluation strategy. Different judge models can assign different scores to the same outputs. Misconfiguration and bias can therefore affect the build decision without appearing as an execution failure. A successful runner establishes only that the evaluator ran, leaving its measurement of the intended property unproven.
EvalSense tests that distinction through controlled perturbations of output texts. Its perturbation tiers include rephrasing without changing meaning, introducing minor content changes, and significantly changing the meaning of the text. The method then measures whether evaluator scores move in the expected direction. Rephrasing provides a test of sensitivity to wording without a corresponding change in meaning, while the other tiers test responses to changes in content.
This approach makes evaluator selection a coverage problem as well as a scoring problem. EvalSense provides an interactive evaluation guide that asks users to specify the risks and requirements of their task, then suggests suitable evaluation strategies. After users select a subset of methods, it generates a coverage report indicating whether those methods comprehensively cover the stated risks and requirements. Perturbation testing addresses whether an individual evaluator responds as intended.
EvalSense demonstrated its domain-agnostic approach in a clinical note generation case study, generating notes from doctor-patient dialogues using a public dataset. The case study showed how meta-evaluation can reveal evaluator failures that would otherwise go unseen. Its implication for orchestration is direct, because running more tasks through a well-designed topology cannot correct systematically misleading judgments. Throughput makes evaluation practical, while meta-evaluation tests whether its conclusions are defensible. Before trusting an LLM judge to gate production deployment, run a perturbation sweep on the system’s own dataset to test the specific failure modes that matter.
Choosing the right combination of framework style and orchestration topology for your system
The final choice combines framework style and orchestration topology. Codebase idiom affects the cost of writing and maintaining tests, while growing evaluation scale can make sequential execution impractical. Diverse evaluators can require specialized sub-runners and pluggable metric contracts. Production coupling adds requirements for trace integration and span-attached scoring. Although framework and topology are distinct decisions, each constrains what the other can support.
For a small Python-native team iterating on prompts, DeepEval in a pytest job with sequential execution and PR-triggered baseline comparison is a suitable starting point. When several teams work with file-configured prompt regression tests, Promptfoo is a good fit, with parallel execution for each prompt variant and commit-triggered runs. These choices follow the existing authoring workflow while matching execution to the scale of the suite. As evaluation expands across models and tasks, parallel or hierarchical execution requires runners with async execution or sharding primitives.
More specialized systems shift the deciding criterion from authoring format to evaluation behavior. A retrieval-focused RAG pipeline fits Ragas with a tracing backend, a nightly full suite, and a PR-triggered subset. For agent capability evaluation that needs sandbox execution, Inspect AI works well under a hierarchical coordinator and a release gate. For a production stack that needs offline-to-online continuity, a platform-bundled framework such as FutureAGI is a good fit, with parallel CI execution, release-gated safety checks, and meta-evaluation of the LLM judge before it is used for deployment gating.
High-stakes deployments also require standardized prompting protocols, fixed model configurations, and meta-evaluated judges alongside threshold gates. Those controls still depend on the data entering the harness. Stale, duplicated, or inconsistently formatted test datasets can distort scores with data problems. Eval data is therefore a system of record that needs the same reliability discipline as the runner and evaluator. The dependable production gate is the whole engineered system.