Training Data Provenance Audits for Hallucination Reduction
Tracing training data back to its sources reveals hallucinations before they reach customers.
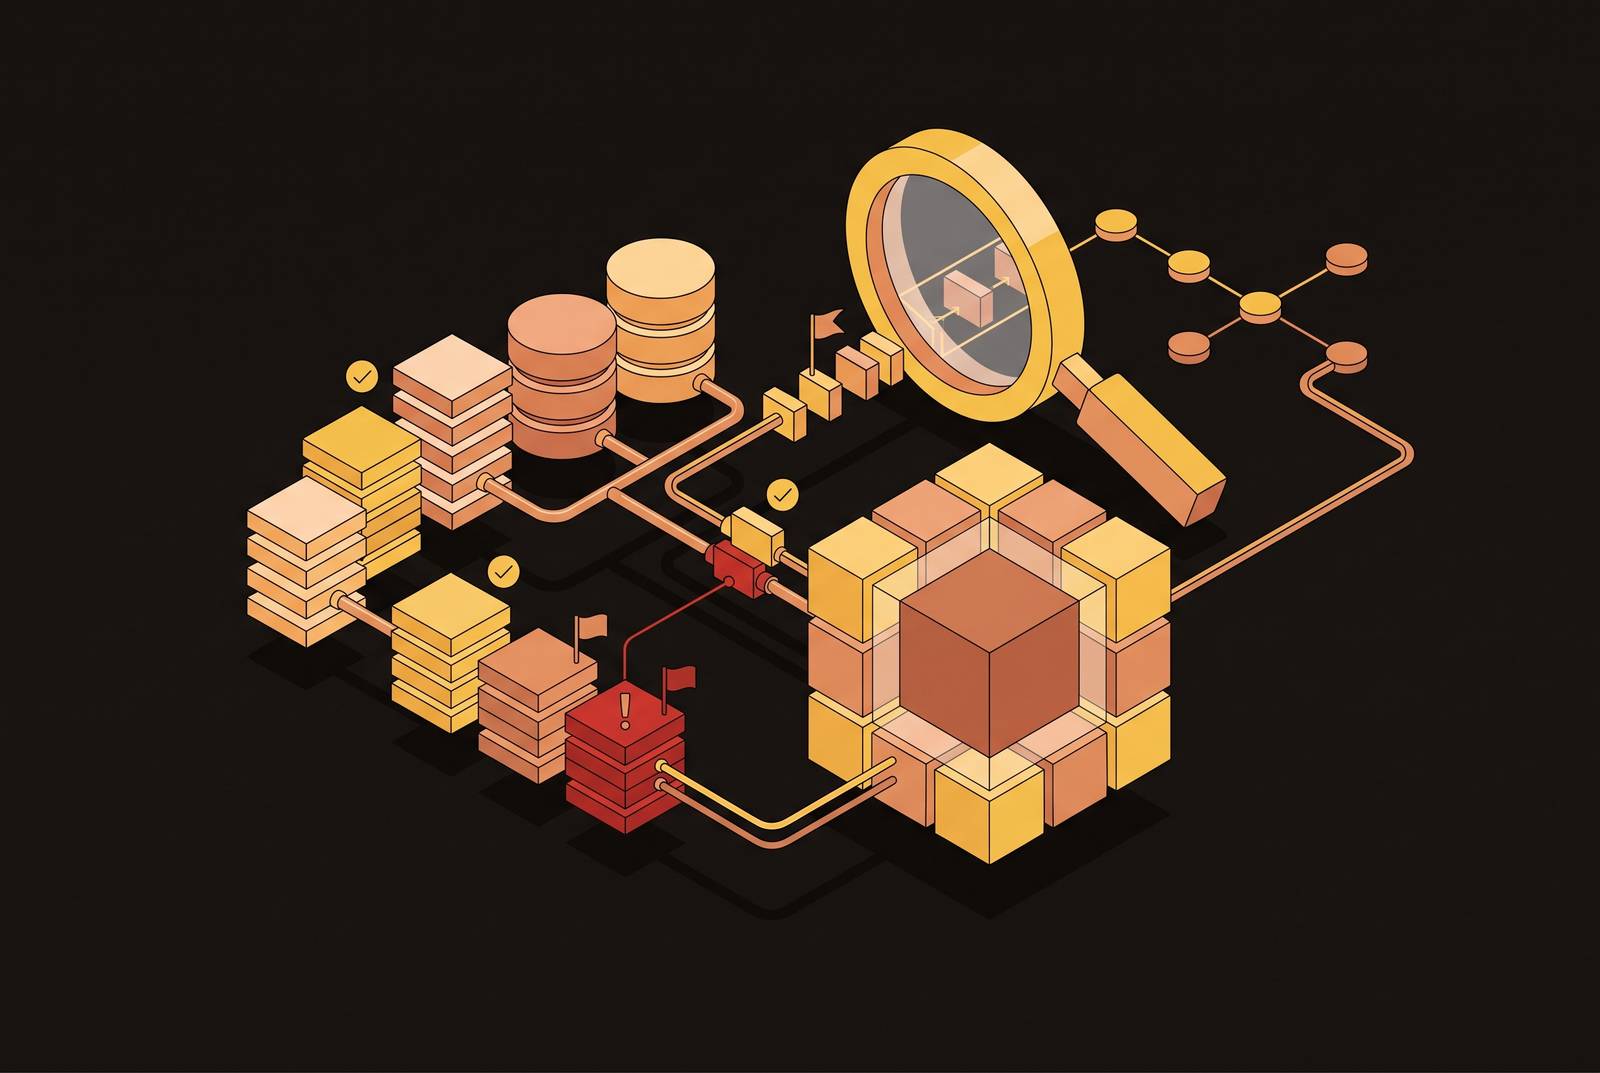
Training data provenance audits address hallucinations at their source. Their value is to trace confident mistakes back to gaps, contradictions, and misattribution in the data, then make remediation targeted. For enterprises, this diagnosis needs continuous monitoring of the data that feeds models and agents to keep working over time.
Why hallucinations are a data problem before they are a model problem
RWS TrainAI describes “hallucination” as a catch-all for behaviors with different causes, including factual fabrication, unsupported inference, and overconfident generalization. Treating these as one model defect obscures the conditions that produce them. Some errors arise predictably from how tasks were defined, how examples were labeled, and what context was missing. Different causes therefore call for different interventions.
Inconsistent labeling teaches the model that answers that contradict each other can all be right, whether they disagree on entity boundaries, negation, or multi-label precedence. Underspecified instructions leave out who the answer is for, what it should do, or what fidelity constraints apply, so the model fills in the missing decision logic with no signal to stop. Long-tail coverage gaps leave rare scenarios out of training, so when they appear, the model tends to generalize from the nearest pattern it has seen. These are upstream data-design failures. Fine-tuning can reshape representations, but it cannot fully remove uncertainty originating in pre-training distributional gaps or capacity constraints.
How benchmark scores hide the severity of the problem in real enterprise conditions
Grounded summarization benchmarks give a model a document and ask it to stay close to that document. Enterprise workflows often require something materially different, which is retrieval from broad, sometimes unverified corpora followed by reasoning and tool use. A score on the first task does not establish reliability on the second.
Multi-step workflows widen that gap because an early error can become the grounding material for later steps. A tool output or contaminated input passes into the next stage, where further reasoning can make the resulting answer sound more coherent without making it more defensible. Additional steps can propagate a mistake whose origin is no longer obvious in the final answer.
Seekr names a procurement measure for this distinction, Cost Per Defensible Output. It shifts attention from benchmark performance to the fraction of outputs an organization can defend to a regulator or auditor. Choosing a model alone cannot answer that question because the evidence behind an answer depends on retrieval and source architecture. The practical lever is therefore not merely choosing a model with a favorable score, but establishing whether the corpus supplying its answers has reliable coverage and attribution.
Why tracing data lineage is the structural intervention benchmarks and output filters cannot provide
Output filters and production monitoring operate after a model has produced an answer. Traditional service monitoring has a narrower limit, because latency, uptime, and error rates do not reveal whether a fluent answer is wrong. A successful API response can therefore coexist with a substantive failure. Provenance auditing addresses the data conditions that make particular failures predictable before they appear as outputs.
The audit traces training and evaluation data back to its sources, checks for gaps and inconsistencies, and links what it finds to how the model is likely to behave. Seekr treats defensibility as a property of source architecture, with attribution extending from outputs back toward training data. The organization needs to be able to inspect the evidence that shaped an answer.
RAG does not remove that requirement. Although retrieval supplies context rather than changing model weights, its corpus still carries coverage, reliability, and attribution risks into outputs, so the same audit method applies. Model collapse shows how content made up by earlier models can enter the data that later generations use, so provenance tracking must continue through each round of ingestion.
What a training data provenance audit covers and how it is structured
A training data provenance audit examines six connected conditions. Together, they describe where data came from, what it contains, how it was interpreted, and whether those facts can be demonstrated. Each condition exposes a different failure, so a complete audit cannot substitute strong documentation for weak coverage or clean labels for uncertain sources.
Source lineage records where each dataset came from, who made it, which license applies, and whether its terms allow the planned use. Its failure modes include misattribution and unlicensed reuse that remain hidden when data is detached from its origin.
Coverage mapping records which topics, domains, languages, and edge-case scenarios appear, and at what density. Its failure is sparse coverage that may go unnoticed on benchmark tasks but produces overconfident generalization in production.
Labeling consistency review examines whether annotation guidelines were applied uniformly across annotators and over time. Its failure is annotation drift, where informally changing rules turn small disagreements into systematic bias.
Contamination checking looks for evaluation data that entered training sets, content ingested from earlier model generations, and adversarial or poisoned samples. Its failure is a corpus with content that makes evaluation less trustworthy or feeds unreliable material into learning.
Representational gap analysis examines whether protected groups, rare scenarios, or low-frequency domains are systematically under-represented. Its failure is uneven representation that produces disparate outputs.
Documentation completeness examines whether all these conditions are recorded in a form that can be produced on demand. Its failure is an audit whose findings cannot be substantiated because the underlying records are missing.
The Data Provenance Initiative provides a public example of lineage work at scale. Its multidisciplinary effort, involving MIT, Harvard Law School, and other academic and legal institutions, traced text datasets through sources, creators, licenses, and downstream use. It also released the Data Provenance Explorer as an open-source tool for filtering and exploring that lineage. This provides a practical reference for source attribution, while the remaining audit components address the suitability of data for a particular deployment.
Where enterprise systems of record introduce provenance risk that general-purpose audits miss
An enterprise system of record introduces ambiguity that a dataset-level source inventory alone may miss. Informally changing annotation guidelines have a parallel in field definitions that shift across sales reps, regions, or system migrations. In both cases, entries that look alike can mean different things. The provenance problem lies not only in where a record originated, but also in whether its meaning remained consistent as people and systems handled it.
A CRM record with a missing industry classification leaves a coverage gap. A duplicate contact with conflicting deal stages supplies inconsistent information, while an account enriched from an outdated source supplies stale context. These are not merely formatting defects when an AI system uses the records to make decisions. They undermine the evidence available for its output on that record.
Agentic RevOps workflows can then carry a hallucinated field update or miscategorized deal stage into pipeline reviews, compensation calculations, forecasts, and board-level reporting. Continuous, autonomous data reliability tackles that risk by finding missing fields, duplicates, and inconsistencies as they appear and suggesting or applying fixes without waiting for human triage. For AI-driven revenue operations, this is a prerequisite for keeping the evidence usable between formal audits.
How regulatory requirements are making provenance audits mandatory rather than optional
The EU AI Act requires training data provenance to be documented for high-risk AI systems. It requires documentation of system architecture, training data, and accuracy metrics. Organizations within scope need records capable of establishing the data and system conditions that a provenance audit examines.
That obligation changes the purpose of documentation from an internal reference to evidence that may need to be produced externally. When a regulator requests an explanation or an incident requires reconstruction, incomplete logs cannot substitute for records generated as the system runs. An account of the training corpus at one point in time can explain later changes only if those changes are recorded too. Continuous audit trails therefore connect technical reliability with the ability to demonstrate how the system was governed, without depending on an explanation assembled after the event.
How to run a provenance audit: the sequence that produces actionable findings
Begin with inventory and source attribution. Compile every dataset used in training and evaluation, recording its origin, creator, license, and ingestion date. The Data Provenance Explorer can accelerate lineage work for standard corpora by providing a public reference.
Next, map coverage and density for each subject domain or task the model serves. Check whether the data covers the conditions the deployment will encounter. Flag thin domains for data augmentation or explicit out-of-scope labeling.
Then review consistency and drift by sampling annotation records across time and across annotators. Identify where guidelines evolved informally and where structurally similar inputs received contradictory labels. These contradictions are evidence of learned ambiguity. Recording the affected dimensions makes the next remediation decision specific.
Follow with contamination and currency checks. Verify that evaluation sets were not present in training data and check for ingested content from prior model generations. Confirm that time-sensitive facts are dated and that the model’s knowledge cutoff is documented and communicated. This separates missing coverage from material that is contaminated or no longer current.
Cross-reference the findings against known hallucination patterns in production, looking for a traceable connection between a specific data condition and a specific class of error. That connection is the audit’s diagnostic result. It provides a basis for prioritizing remediation rather than changing data on the assumption that any improvement will address the observed failure.
Finally, record findings for internal governance and regulatory audit needs, and establish a cadence for reassessment as data or model versions change. For CRMs, periodic review needs continuous monitoring because fields change, duplicates accumulate, and enrichment sources become stale between cycles. The audit establishes the baseline, while an agentic data reliability layer detects departures and proposes or applies fixes.
What organizations get wrong when they treat the audit as a one-time compliance exercise
A pre-deployment gate establishes what was true at the time of the audit. Data drift can move production inputs away from the training distribution, turning documented coverage into an unrecognized gap even if the training corpus itself has not changed. Later ingestion can bring in AI-generated content from earlier model generations. Agentic workflows can also turn a previously limited source problem into a failure that propagates through several reasoning steps. Each path weakens the value of a static finding.
Teams have a strong practical reason to object: they cannot keep running a full audit of every dataset. Continuous monitoring requires instrumenting the data layer to detect changes and flag the conditions associated with known failures. This preserves the audit’s diagnostic work while directing attention toward the parts of the baseline that have shifted.
Source-controlled architecture helps teams do this by showing the sources behind outputs and letting them refine which sources are allowed in production without retraining. In systems of record, the same reliability treatment must reach every record update, contact merge, and enrichment-source change that alters the provenance baseline.