Embedding Space Drift Monitoring for Pre-Release Evaluation
Catch retrieval failures before release by monitoring embedding drift against production data.
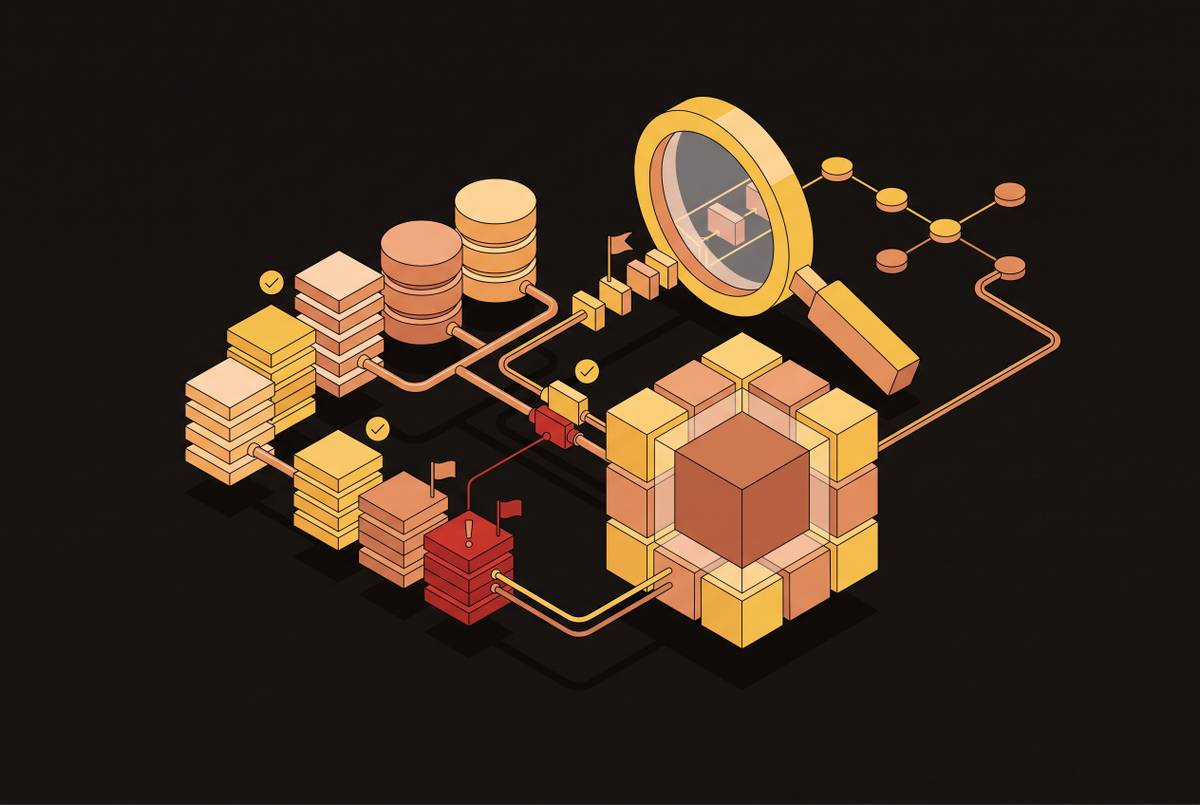
Embedding space drift monitoring belongs in pre-release evaluation, where it can stop silent retrieval failures before they affect users or autonomous actions. Its value comes from combining distributional signals with direct retrieval checks against versioned production data. A release gate built this way tests whether the candidate system still retrieves the right evidence.
Why embedding drift is a silent retrieval failure, not a visible error
The dashboard is green, but the answers are getting worse. The vector database responds quickly, the retriever returns chunks, and the LLM produces fluent text. Yet a support assistant answers a billing question with an outdated policy page, or a compliance reviewer retrieves a regulation from the wrong jurisdiction. The failure is semantic.
Embedding drift changes which documents sit near a query, or what a similarity threshold that has been accepted means. Developers see confusing RAG traces while SREs see stable latency beside rising escalations, so neither view alone explains the degradation. In an agentic system, the consequence can extend beyond an answer. Retrieval feeds planning, planning feeds tools, and tool outputs feed later retrievals, so one bad neighborhood can throw off the decision chain.
The three distributional signals that actually measure drift
Embedding distribution drift, nearest-neighbor churn, and similarity-score collapse each show a different part of how retrieval can fail. They need to be read together. For distribution comparisons, cosine distance is generally preferable to Euclidean distance because embeddings are typically compared by directional alignment. Euclidean distance can still detect drift effectively, especially on normalized embeddings. The choice should reflect how the retrieval space is used.
Distribution drift measures changes such as centroid shift, covariance change, or Jensen-Shannon divergence against a baseline dataset version. Nearest-neighbor churn then tests whether those changes alter the retrieved neighborhood, measured as the percentage of queries whose top-k document IDs changed. Spearman's rho on neighbor rankings detects reordering even when the same documents remain present. Rank correlation below 0.85 is a practical reference for significant drift, though the appropriate threshold depends on domain and embedding dimensionality.
Similarity-score collapse adds the distance from retrieval results to the acceptance threshold. Top-1 and top-k score distributions should be tracked by route, corpus, language, and tenant. Scores compressing toward the threshold can warn of degradation before retrieval quality visibly deteriorates. Conversely, a centroid can move without changing any retrieved documents. That is why no single signal establishes retrieval failure.
Why centroid shift alone misses cohort-level failures
A global centroid that stays the same can hide a sharp drop in quality for minority-language, long-tail, or domain-specific queries. The mean masks the tail of the distribution. ContextRelevance may hold for common queries while falling for a smaller cohort, leaving an aggregate score apparently healthy. Monitoring therefore needs slices by intent, tenant, language, and corpus version.
A new cluster with many production traces but no golden-set neighbor indicates dataset rot, because the accepted test set no longer represents that part of actual use. Identifying the gap before release allows it to become a backlog item before it causes a user-reported failure.
Per-cohort analysis adds engineering work, but it does not have to use a separate collection pipeline. Production spans already containing session ID, user ID, and intent tags provide the slicing surface. The trace store can also supply the input-distribution feed. The remedy is evaluation discipline as much as better mathematics.
The case for running drift checks before release, not after deployment
Answer-faithfulness scoring runs after retrieval, while embedding monitoring can detect retrieval-space changes before generation. A failure found before promotion has not yet influenced user sessions, downstream agent actions, or automated decisions. Once deployed, the same failure may already have propagated through actions performed at machine speed. An alert after launch cannot undo that exposure.
The strongest objection is that only production traffic provides a realistic test distribution. A rolling centroid from recent production traces, paired with a versioned golden set, anchors the comparison to actual use. The candidate release is evaluated against that evidence before it reaches users. Production supplies the test distribution without becoming the first place the candidate is judged.
That comparison also requires explicit embedding-model version pinning at deployment. When a provider changes a model without notice, it can look like data drift even though the model itself changed. The baseline then becomes an unreliable comparison point. Pinning the version separates an intentional candidate change from an untracked change in the system being evaluated.
When to trigger a drift check in the release cycle
A change to the embedding-model version should trigger evaluation right away, before promotion. Different models create incompatible spaces, so raw vector comparisons against the prior model can be meaningless. The baseline must be rebuilt for the new space, or the check must compare retrieval outcomes instead. Fine-tuning also warrants this evaluation, because a candidate can regress without a switch to a different general model.
A corpus re-index or chunker change needs the same immediate treatment. BM25 or embedding overlap on top-k results against the dataset baseline can reveal whether previously retrievable documents have moved out of reach. Reproducibility requires storing the exact corpus snapshot, chunker version, model, and threshold at that point so a failed comparison can be reconstructed.
Prompt-template changes also need evaluation after any update to a system-message, few-shot block, or tool-schema. The golden set wraps inputs in a particular template, so an old template tests a contract that no longer matches production. Generic rubrics can still give scores that look sound for either contract. The golden set itself should therefore be versioned like source code, with a changelog recording which intents were added and why. A version label names an evaluation artifact that can change over time.
Building the pre-release evaluation gate: signals, thresholds, and the retrieval precision check
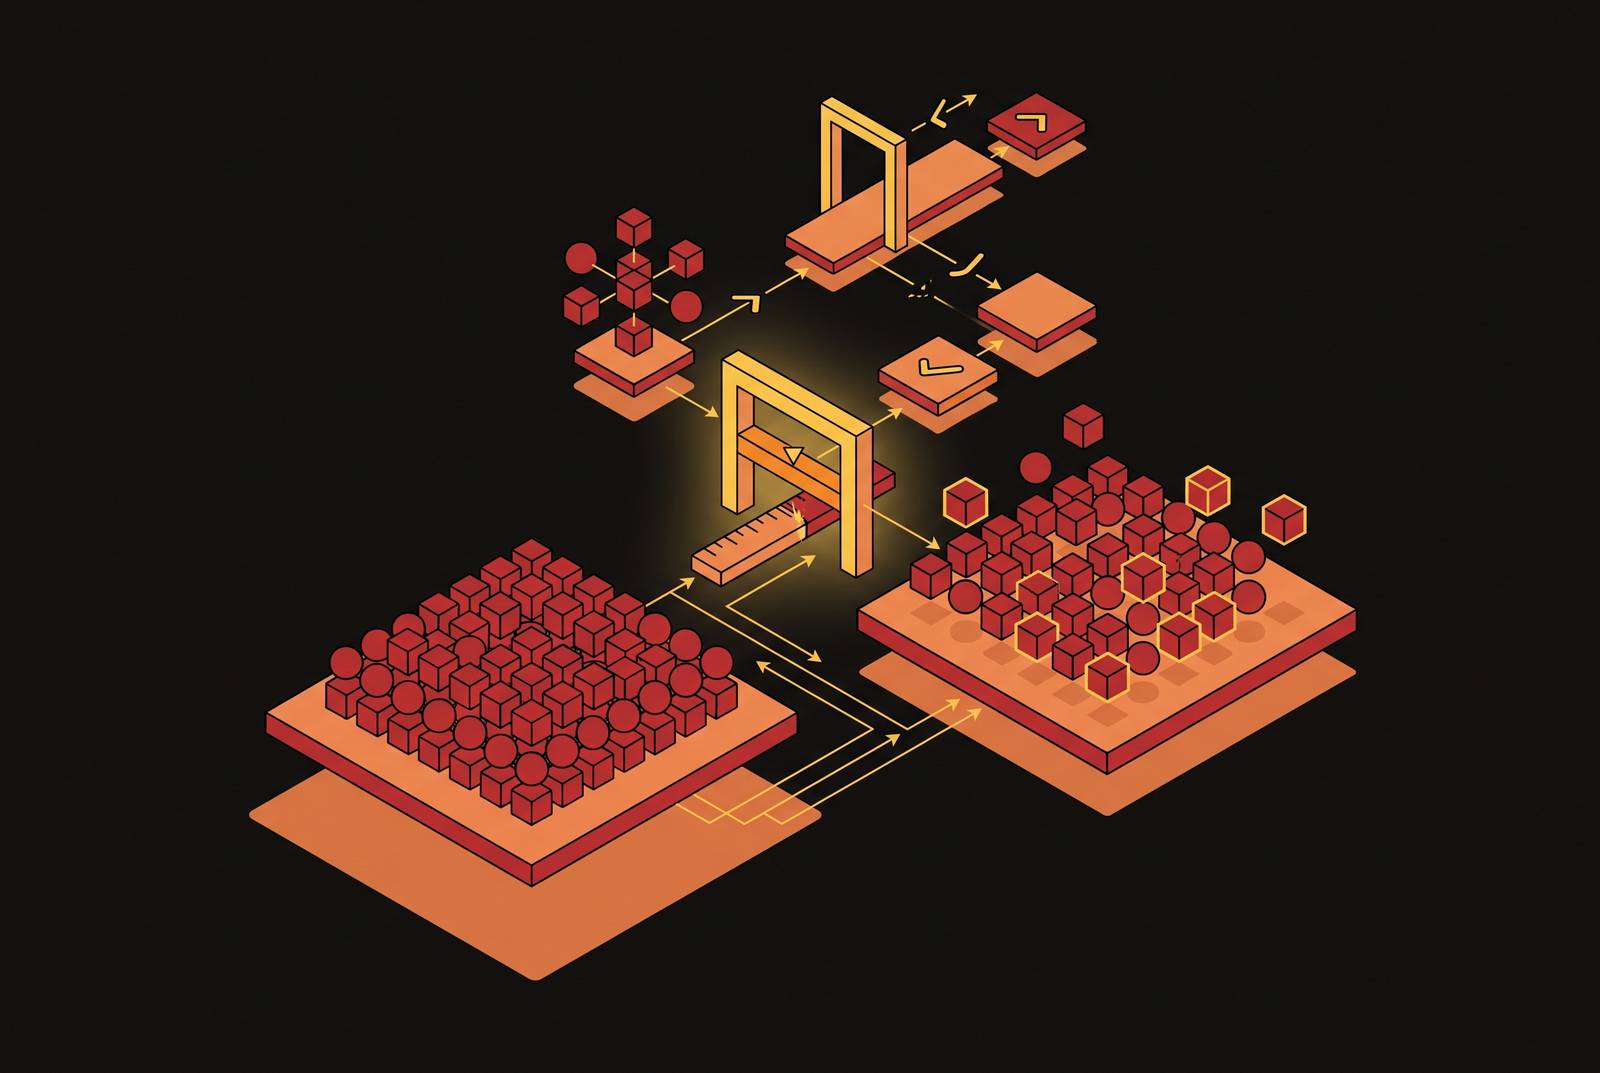
A defensible gate has two layers, which are distributional checks and a retrieval precision sample. The first detects movement and helps locate it. The second establishes whether the movement has changed the relevance of the documents users receive. Both are needed because a geometric shift can be harmless, while an aggregate distribution can hide wrong-context retrieval.
For the distributional layer, centroid cosine distance can be compared with a 30-day baseline, using a rolling 7-day production centroid and alerting when the distance crosses two standard deviations. KL divergence on intent labels provides sharper attribution of which query classes are changing. Neighbor churn should include Spearman rank correlation across the probe set alongside set overlap. Similarity-score distributions are still split by route, corpus, language, and tenant. Aggregating them would discard the very differences the gate needs to expose.
The precision layer runs probe query-context pairs through the pipeline and scores each for binary relevance through human or LLM-as-judge evaluation. This adds cost and latency to release evaluation. EmbeddingSimilarity should be paired with ContextRelevance because similar wording can still point to the wrong document. Probe sampling should include low-confidence spans, escalations, and abandoned sessions alongside successful answers.
Every comparison must be reproducible from its artifact record. The gate needs a record of the corpus snapshot, chunker version, embedding-model version, and index version used for both the candidate and the baseline. Those records distinguish a change in the data from a change in how it was represented or retrieved. Without them, a failed score is difficult to diagnose.
Thresholds must be set before deployment. They include acceptable semantic drift tolerance, maximum neighbor churn, a minimum ContextRelevance floor, and a maximum retrieval empty rate, with breaches blocking promotion.
What the gate catches that MTEB leaderboard scores do not
MTEB leaderboard performance does not establish fitness for a particular retrieval corpus. The corpus can differ from public benchmark corpora in its domain vocabulary, document length distributions, and label granularity. A model that separates broad topics well may still fail to distinguish near-duplicate legal clauses. The distinction is small in wording but decisive for retrieval. Only evaluation against the relevant queries and documents tests that requirement directly.
Public benchmarks remain useful for comparing candidate models, but they cannot replace domain-specific pre-release evaluation. A leaderboard-only choice leaves the production performance gap unmeasured. Fine-tuning on domain-specific labeled pairs is another reason to keep the gate, since the model still needs regression testing after it has been adapted. Acceptance depends on the candidate's behavior on the task.
Retrieval metrics make that behavior more explicit beside the distributional signals. Recall@K measures the fraction of all relevant documents that appear in top-K results, while MRR measures the average reciprocal rank of the first relevant result across queries. NDCG supports graded relevance when some results are more relevant than others. Cohort-level results then show whether a candidate's apparent improvement excludes a language, intent, or domain.
How dirty upstream data compounds embedding drift — and why systems of record are the upstream
Embedding drift can originate in the systems of record that supply the retrieval corpus. Incomplete, stale, or inconsistently structured CRM and RevOps records pass those defects into indexed documents and chunks. As the records change inconsistently, their embedding distribution can change for reasons unrelated to an intentional model update. The gate detects the resulting symptom in retrieval. It does not, by itself, repair the source data.
This distinction changes how a failed evaluation is interpreted. AI tools already produce wrong outputs when the CRM records they depend on are incomplete or stale. A retrieval corpus built from those records can then drift as the same defects spread through updates. In agentic systems, an incorrect retrieval can drive a record update, lead-routing decision, or scheduled follow-up without a human checkpoint.
Addressing only the embedding layer leaves that source of change intact. A rebuilt index can still represent unreliable records, and later updates can reproduce the drift. The response must therefore address data quality in the system of record when that is the cause.
What to do when the gate fires: rollback, rebuild, or re-baseline
The response depends on whether the failed signal indicates degradation or legitimate evolution. High neighbor turnover together with falling ContextRelevance calls for rollback to the last accepted embedding model or index. The index should be rebuilt under the prior model version, and the gate rerun before the candidate is promoted again. A failed candidate should not become the new reference simply because it is newer.
A shifted centroid with stable retrieval precision supports a different response. The change may reflect legitimate corpus evolution. In that case, the golden set can be re-baselined against the new distribution, explicitly versioned, and accompanied by a documented decision. Re-baselining preserves a meaningful comparison point for an intentionally changed system. It is not a way to make a failing gate green.
When scores collapse for one language, tenant, or intent while global metrics hold, the response should stay cohort-specific. The affected index slice can be rebuilt, or cohort-specific evaluation rows added before re-promotion. Where retraining is needed, the loop also requires fresh labeled evaluation data and A/B testing before promotion. Retraining on the same shifted distribution without fresh labels can leave the gate permanently degraded.
The final constraint is the speed of corrective action. Rollback in a well-instrumented system should be a pointer move that avoids a redeployment cycle. An alert that requires a full release cycle to address is nearly as bad as no alert. Versioned artifacts make rollback, cohort rebuilds, and deliberate re-baselining actionable by preserving which version, which model, and since when.